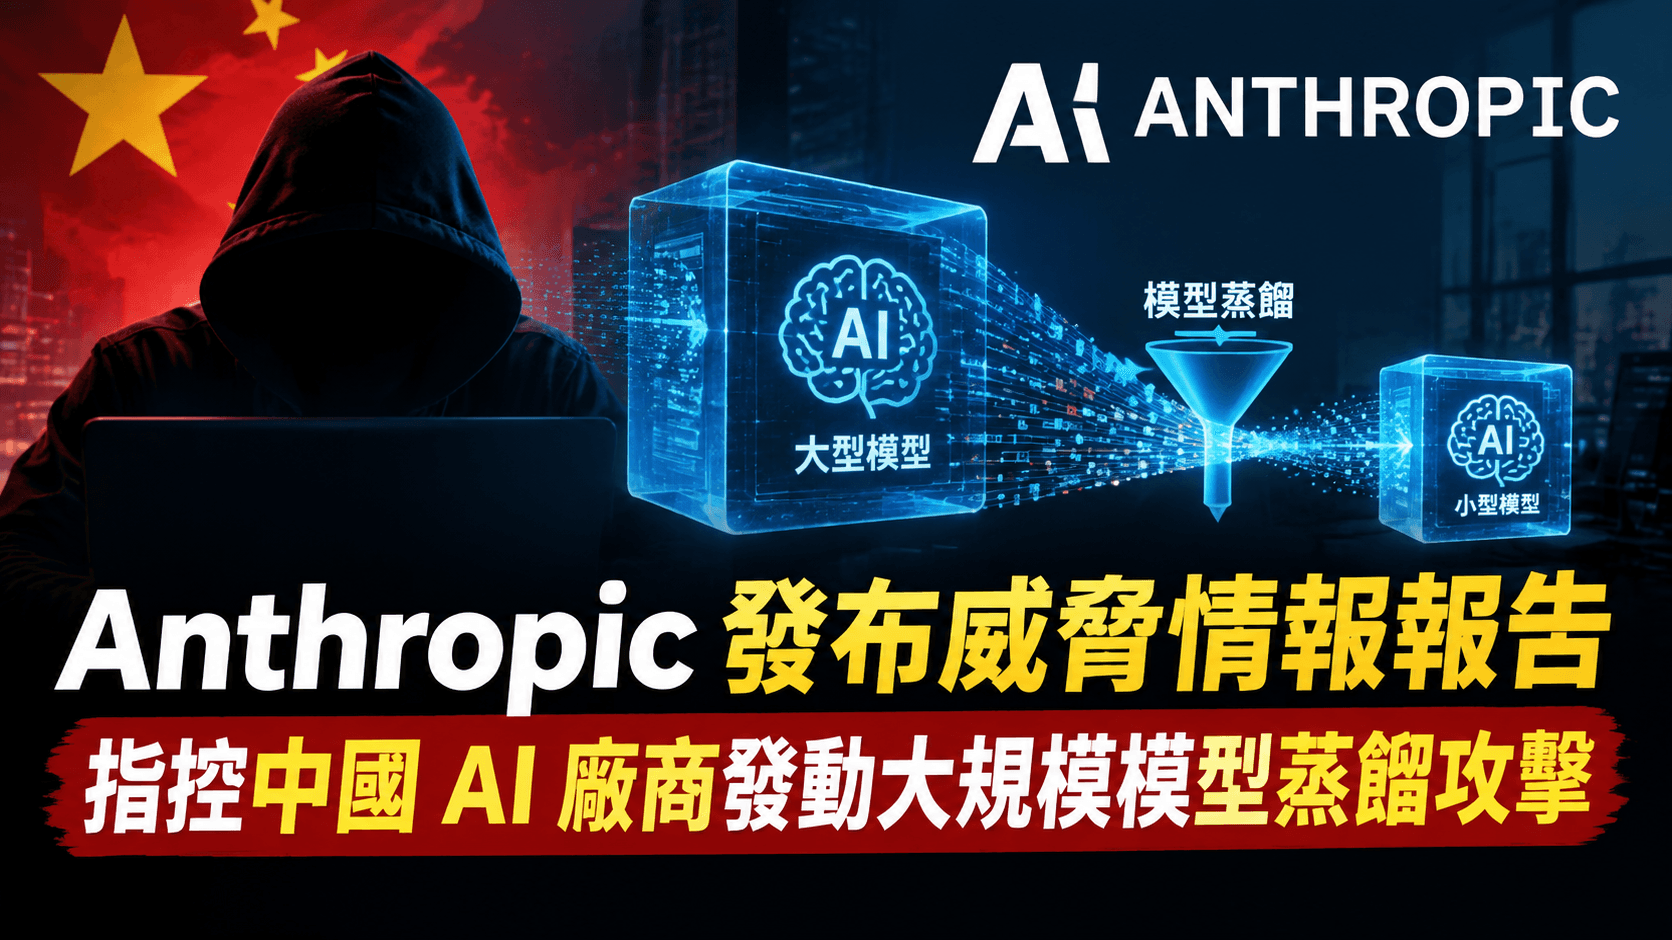
The battle over technical moats among the world's AI giants has officially evolved from a pure compute race into a new kind of digital offense and defense. US AI leader Anthropic stated publicly in its newly released threat intelligence report that several leading Chinese AI labs are launching unprecedented large-scale "distillation attacks" against its flagship model Claude. Using systematic prompt engineering and reverse engineering, this extraction campaign targets Anthropic's most important technical moat: its chain-of-thought (CoT) reasoning and autonomous agent capabilities.
According to Anthropic's monitoring data, the attacks were not occasional one-off probes but highly organized, industrial-scale data collection with clear training goals. Attackers used thousands of fake accounts to get around the platform's defenses, sending nearly 200 million conversation requests in total. Their ultimate aim was to cheaply transfer the complex logical reasoning, code review and tool-use architecture Anthropic spent hundreds of millions of dollars developing into China's domestic open-source and commercial large language models.
The incident not only exposes the deep tension in the generative AI industry between "shortcut innovation" and original research, but also sounds an alarm for the semiconductor and software industries in the Asia-Pacific region and Taiwan. Now that distillation of frontier algorithms has become a supply-chain-level intelligence war, cloud providers and model developers urgently need to redefine their intellectual property and API protection strategies.
Key takeaways
- Large-scale attacks exposed: Anthropic detected 5 separate distillation attacks totaling more than 200 million conversation requests.
- Alibaba and Moonshot AI involved: Alibaba used 3,500 accounts to send 151 million requests; Moonshot AI called the top-tier Opus model 300,000 times within 10 days.
- Core technology targeted: the attacks focused on Claude's chain-of-thought reasoning, autonomous agents, code analysis and tool-use architecture.
Industrial-scale data extraction: how distillation attacks work
Model distillation was originally a standard machine-learning technique for shrinking models and improving inference efficiency at the edge, but it has now been turned into a highly efficient weapon for copying technology. Used legitimately, distillation lets developers condense the abilities of a large "teacher model" into a smaller "student model." But when an unauthorized third party uses automated scripts to call a rival's top models at scale and systematically extract their "thinking process" and intermediate reasoning steps, it amounts to real intellectual property infringement and a security threat.
In its technical review, Anthropic found that the attacks precisely targeted the strengths of its Claude models, including multi-step reasoning, long-context code debugging and coordinated use of external tools. With carefully designed prompts, the attackers coaxed the model into outputting complete, highly structured chain-of-thought data. These high-quality reasoning traces are the most expensive golden datasets for training new reasoning models, and the hardest to get through ordinary web crawling. This way, attackers can absorb, at very low inference cost, the results of years of alignment and reinforcement learning by pioneering companies.
Big names emerge: the record on Alibaba and Moonshot AI
Of the five separate attack operations Anthropic disclosed, the data collection by Alibaba and startup unicorn Moonshot AI was by far the largest. The report details that between May and July 2026, Alibaba used as many as 3,500 separate accounts to send a total of 151 million requests to Anthropic's cloud servers, with a single-day peak approaching 3 million. This huge flow of synthetic data is strongly suspected of being fed directly into the training pipelines of its Qwen open-source and proprietary model family, sharply narrowing its gap with top Western models in complex reasoning.
Meanwhile, Moonshot AI, the rising Chinese AI star known for long-context processing, took a dense, specialized blitz approach. In just 10 days, the team used more than 5,000 accounts to send nearly 300,000 high-end requests targeting Anthropic's flagship Claude Opus model. Even more striking, these included many highly sensitive multimodal image tasks asking the model to analyze CCTV surveillance footage. This involved not only reverse-extracting the model's capabilities but also crossed multiple red lines on data compliance and algorithmic safety.
Market impact and geopolitical strategy: lessons for Taiwan's tech ecosystem
This model extraction war, fought behind cloud APIs, shows that the contest between "original developers" and "low-cost followers" in the global AI race has reached a fever pitch. For the global market, the spread of distillation attacks means the defenses of top closed-source models are being severely tested. If leading companies cannot effectively protect their chain-of-thought data, the return on their huge pre-training investment will be badly eroded. This could force frontier labs such as Anthropic and OpenAI to further tighten API access, raise monitoring thresholds and even hide more reasoning details.
This trend also has far-reaching implications for Taiwan's tech industry and corporate digital transformation. As a global hub for semiconductors and server hardware, Taiwan is actively moving into enterprise generative AI applications and sovereign AI software development. As international model defenses get stronger, Taiwanese companies building hybrid cloud architectures and integrating third-party large language models need to pay more attention to API audit logs, cross-border data compliance and endpoint data protection. Taiwanese R&D teams developing domain-specific models should also set transparent, compliant data governance standards to build a reputation as trustworthy AI partners in the international supply chain.
Frequently asked questions (FAQ)
What is an AI model distillation attack, and how is it different from legitimate fine-tuning?
An AI model distillation attack is when an unauthorized outside organization uses automated programs to call a top target model's API at scale, systematically collecting its high-quality outputs and chain-of-thought reasoning data to train its own competing model. This is different from officially authorized fine-tuning or legitimate fine-tuning on your own private data: the former is essentially reverse engineering that evades terms of use and takes other people's research results.
Why did the attackers specifically target Claude's chain of thought and agent capabilities?
Because high-quality logical reasoning, complex code generation and autonomous agent tool use are the core abilities that are hardest to train from public web data. Claude's excellent performance on long context and logical reasoning makes its detailed problem-solving traces the ultimate high-value source of synthetic data for training new reasoning models.
Will this incident change how open cloud AI APIs are worldwide?
Very likely. To block similar industrial-scale reverse extraction, leading AI providers are bound to introduce stricter anomaly-detection algorithms, limit full visibility of reasoning steps, and apply tighter identity verification and rate limits to high-frequency, distributed API accounts.
With Anthropic officially defining model distillation as a serious security threat and making it public, the rules of the AI race have reached a turning point. In the future, an AI company's competitiveness will be measured not only by parameter counts or benchmark scores but also by its defense-in-depth ability to protect core intellectual assets and identify malicious reverse-engineering traffic. In a complex game where open and closed source, originals and imitations intertwine, only ecosystems that combine technical innovation with security resilience can stay ahead in the long race of this intelligence revolution.


